Four billion documents, 40 days after two billion
Lyrenth's index passed four billion AI-ready documents across 170 million domains, 40 days after it passed two billion. Here is what doubling that fast changes for the agent reading it.
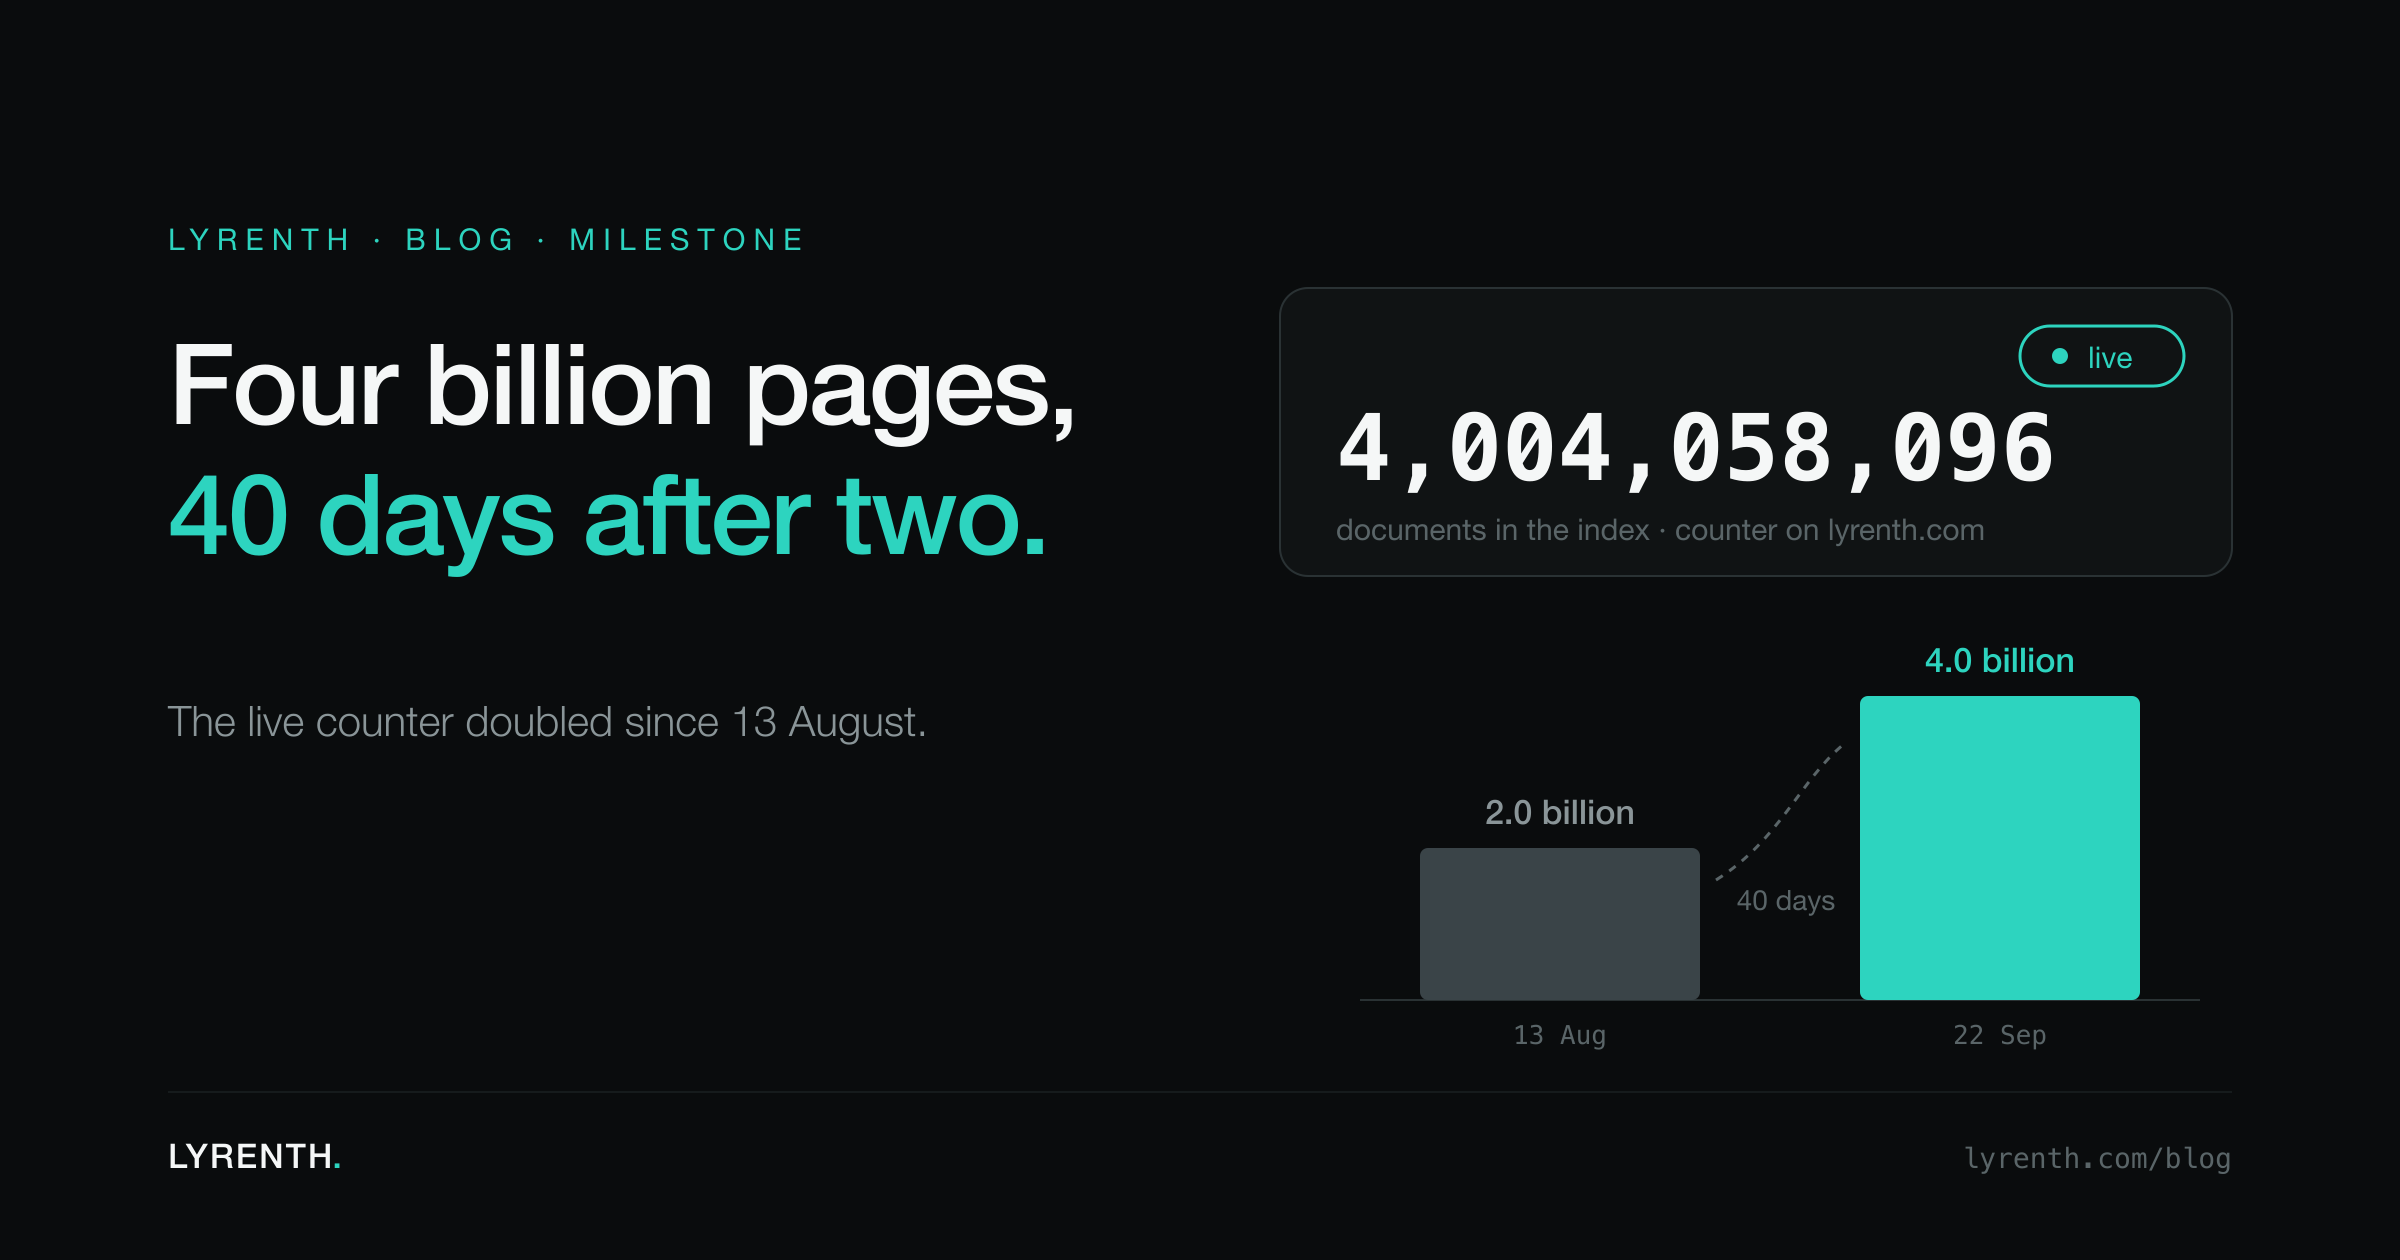
Today at 11:19 UTC the counter on our front page read 4,004,058,096 documents across 170,384,783 domains.
On the morning of 13 August it read 2,000,432,308, and we wrote about passing two billion. The index doubled in 40 days, an average of about 50 million new documents a day.
Each of those documents is a web page already fetched, rendered when it needed rendering, cleaned of its menus, banners and scripts, and stored as an AIDocument: the content of the page in one stable shape that an agent reads in a single request. The counter is live on lyrenth.com and on the index stats page, and it is public on purpose. A number you can check is worth more than one you are told.
What doubling buys an agent
The size of an index matters for one reason: the next page your agent asks for.
When that page is already in the index, the read is served in a fraction of a second, at a fraction of the tokens of the raw page, and the site is not contacted again. When it is not, it is fetched once, by a crawler that identifies itself and follows the site's rules, and it becomes an instant read for everyone who asks after you. Crawl-on-miss, explained walks through both paths.
Twice the documents means the first case happens far more often. That is the whole product: coverage is the difference between a cache that sometimes helps and an index you can build on.
Breadth, not only depth
170 million domains is the half of the number that is easy to skip.
An index can grow by crawling a few enormous sites deeper and deeper, and the counter would climb just the same. Ours grows across the web: company pages, documentation, shops, local businesses, forums, public records and small publications. That long tail is where agents actually go, and it is where a large index is most useful.
Checked, not announced
We did not write this because a slide said four billion. We wrote it because the public counter did, and anyone can watch it move.
Read any URL and see what comes back. Reading from the index starts free: 2,000 documents a month, no card.